Search autocomplete is just counting, not predicting
Related to: Search Autocomplete can point to a category, not just finish your words
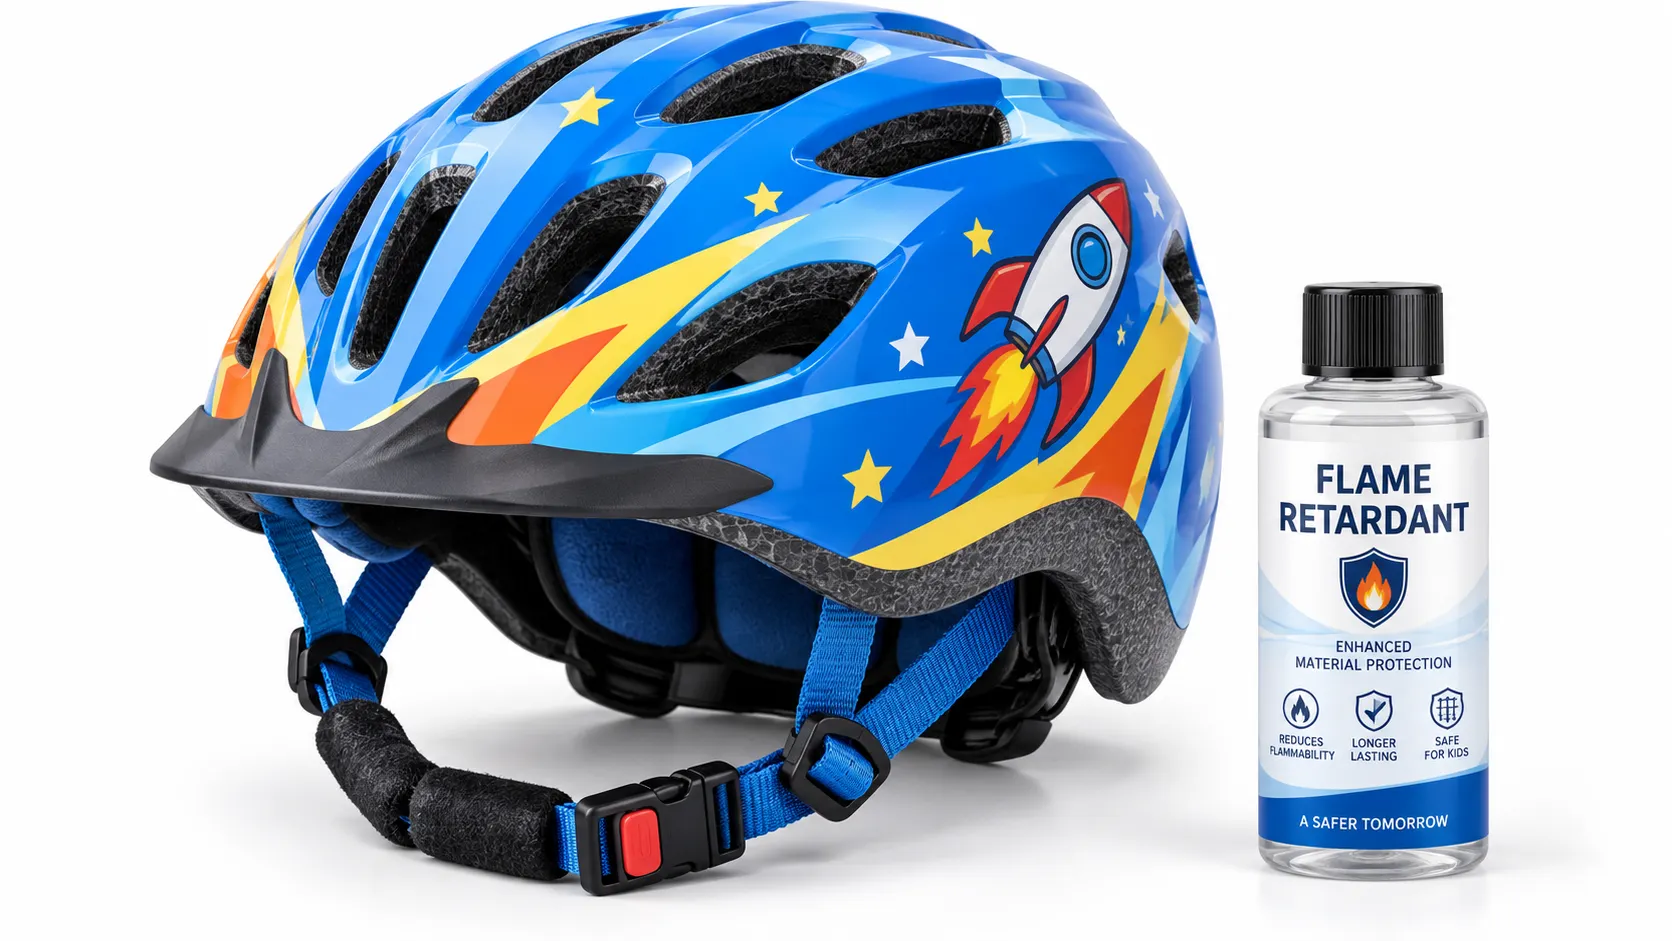
An online retailer’s search box had a problem that only showed up in demos nobody meant to give. Type “kids bi”, and the dropdown confidently suggested “kids bicycle helmet flame retardant”. Nothing on the site matched. The suggestion wasn’t wrong exactly — grammatical, on-topic, plausible — it was just invented.
The autocomplete ran on a sequence-to-sequence model, the architecture family used for machine translation, trained to predict how a partial query continues. Fit on historical query logs, this seemed reasonable: generalize to prefixes it hadn’t seen verbatim. In practice, “generalize” and “invent” were the same behavior wearing different clothes — the model returned things that sounded like what people had searched for, not things they actually had. Nobody could tell from a single suggestion; it took a customer hitting zero results to notice.
The fix was almost insultingly simple: a trie. A trie is a tree where each path from the root spells out a prefix, and any node can be marked as the end of something real — a standard first-year data structure, usually taught for spell-checkers.
The trie was built from the query log, restricted to phrases that had actually led to a purchase, each carrying a weight for how often it converted. Typing “kids bi” walked the trie to that prefix and returned the completions with the highest weight underneath it. If nobody had ever bought anything down the “flame retardant” branch, no such suggestion could exist. The structure can’t hallucinate; it only returns paths that were put there.
The weighting mattered as much as the trie itself. An earlier version weighted by raw query frequency, surfacing typos ahead of the correct spelling, since misspellings compound quietly. Weighting by conversions meant a completion had to be popular with people who actually finished the task — and it was easy to defend internally, since anyone could read the trie and see why a suggestion appeared, no vectors or attention weights to interpret. Debugging became a lookup, not an investigation.
The catch: a trie only knows what’s already happened. It offers nothing for a genuinely new prefix until purchase history accumulates. The model’s worst flaw, inventing nonsense, was also its only advantage: it could say something about a prefix it had never seen. The trie says nothing at all, which is safer, but cold-start queries still need a fallback.
Comments
Join the discussionNo comments yet. Be the first to comment.