Let the clicks speak, a simple popularity-driven ranking
Every click a user makes is a small confession. It says: this is what I wanted, or at least what I was willing to try. When we’re building search and recommendation systems, that confession is one of the most honest signals we have — arguably more honest than the queries themselves, because intent is fuzzy but a click is a decision.
The temptation in modern ranking systems is to generalize. We train models to learn latent patterns, to predict relevance for queries and products we’ve never seen before, to smooth over the noise of individual events. This is powerful - but it comes with a cost. Generalization pulls results toward the mean. It flattens the long tail. The more a model tries to generalize, the more it tends to converge on a narrow set of “safe” answers, and diversity in the result set quietly erodes.
There’s a class of situations, though, where we don’t need to generalize at all — where raw interaction data is already a strong signal on its own. Think about popular search queries, where enough volume has accumulated that patterns are statistically stable. Think about upselling or crossselling popular products, where the goal is explicitly to surface what’s already working. In all these cases, historical interactions can be used directly, without waiting for a generalized model to catch up.
So how do we turn raw clicks into something usable? Start with a baseline: the global click-through rate by position — the well-known fact that position 1 gets clicked far more often than position 10, regardless of relevance. Using this baseline, we can define the expected number of interactions for a product A with respect to a given search or product page: sum up the positional CTR for every impression where A appeared, at whatever position it was shown.
In formula form, if product A appeared in impressions at positions \(p_1, p_2, ..., p_n\) and CTR(p) is the global click-through rate for position p, then:
$$Expected(A) = \sum_\text{for every impression of A} CTR(p_i)$$
In plain terms: for each time A was shown, ask “how many clicks would an average product get from that spot?”, then add those up. If A was shown three times — once at position 1 (\(CTR(p_1) = 0.30\)), once at position 3 (\(CTR(p_3) = 0.10\)), and once at position 8 (\(CTR(p_8) = 0.02\)) — its expected interactions are \(0.30 + 0.10 + 0.02 = 0.42\). That’s the “should” number: how A ought to perform if it were perfectly average, given where it happened to be placed.
The numerator is simple: the actual count of interactions A received — call it $Actual(A)$. Divide the two, and you get a score:
$$Score(A) = \frac{Actual(A)}{Expected(A)}$$
This is a ratio of observed performance to expected performance, adjusted for where the product happened to be shown. A score of 1.0 means “performed exactly as expected.” Above 1.0 means “outperformed its position.” Below 1.0 means “underperformed.” A product buried at position 9 that still rack up clicks will score higher than an identical product parked at position 1 that barely gets touched — because the bar it had to clear was much lower.
One wrinkle: products with very few impressions produce noisy, unstable ratios. A product shown once that got one lucky click scores 1 / 0.02 = 50 — absurdly high, and meaningless. The fix is a familiar one from Bayesian statistics — add a smoothing constant K to both the numerator and the denominator:
$$Score_smoothed(A) = \frac{Actual(A) + K}{Expected(A) + K}$$
Here, K acts as a small dose of synthetic “average” evidence. When Actual(A) and Expected(A) are both large, adding K barely moves the needle — the score stays close to the raw ratio. When they’re both tiny (a brand-new or rarely-shown product), K dominates and pulls the score toward 1.0, i.e. toward “assume average until proven otherwise.” It’s the same idea behind Laplace smoothing: let the data speak, but don’t let small samples shout too loudly.
The resulting score is deceptively versatile. It can be used directly to rank products — a fast, interpretable, model-free baseline. Or it can be folded in as a feature into a larger learning-to-rank system, giving downstream models a pre-digested signal of “how well is this actually performing, relative to expectations.”
A concrete example: “men jeans”
Press enter or click to view image in full size
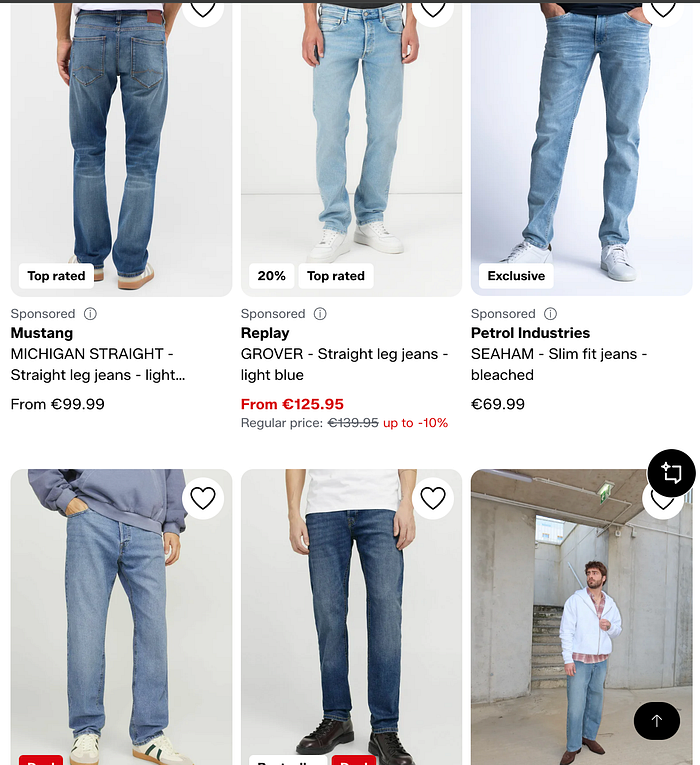
A relevance model trained to generalize has learned that blue jeans are, on average, the safest bet — so the top six results are all near-identical blue jeans from different brands. They’re not wrong, exactly, but they’re redundant. A user looking for black or red jeans has to scroll past a wall of blue to find what they actually want. This is the diversity problem in action: generalization converged on a mean, and the mean is boring.
Now apply the score. Suppose one of those six blue jeans has been sitting at position 2 for weeks, racking up clicks roughly in line with what position 2 should get — its score hovers around 1.0, unremarkable. Meanwhile, a black jean buried at position 9 — a position with low expected interactions — has quietly been pulling in clicks well above what position 9 predicts. Its Actual(A) is small in absolute terms, but its Expected(A) is even smaller, so Score(A) comes out well above 1.0. That black jean is outperforming its placement.
Re-rank by score instead of raw popularity or a purely generalized relevance prediction, and that black jean — along with other underplaced but well-performing items — rises toward the top. The blue jeans that were merely meeting expectations don’t get penalized, but they stop crowding out everything else. The result set naturally spreads across colors and styles instead of clustering on one “safe” answer, because the score rewards items that beat their odds, not just items that are popular in the aggregate. Diversity, in this case, isn’t imposed by a separate re-ranking rule — it falls out of correcting for position bias.
Comments
Join the discussionNo comments yet. Be the first to comment.